


The Hotel Appeared in 30 of 36 AI Recommendations — Yet Had a Blind Spot
Yet the Hotel Was Almost Invisible to One Important Guest Segment

An article by Mark Peter Gasparik
An anonymised hotel audit demonstrates why apparently good AI visibility may conceal a serious commercial blind spot.
An AI recommendation audit of a Hungarian wellness hotel tested 21 questions across two AI systems, with two repetitions per question. That yielded 84 answers.
Of those, 36 involved requests for hotel recommendations without mentioning the property's name. The aim was to see whether the AI systems would suggest the hotel spontaneously based on guests' needs.
The hotel appeared in 30 of those 36 answers.
ChatGPT mentioned it in 15 of 18 cases, and Google AI Mode also mentioned it in 15 of 18. At first glance, this looks like a very strong result.
But a different picture emerged when answers were broken down by guest scenario. The property appeared consistently in questions aligned with its strongest attributes, yet was recommended in only one of four answers concerning a family holiday.
The aggregate AI visibility rate was therefore good, while the hotel remained almost invisible in a commercially important segment.

The Headline Number Looked Good. The Diagnosis Was Missing.
An overall percentage can be reassuring. The detailed breakdown showed, however, that recommendation performance depended heavily on the travel situation described by the guest.

These figures are not market probabilities or a permanent AI ranking. They are recurring patterns observed in a diagnostic test.
The management question is therefore: what happens when a hotel is absent from AI recommendations in precisely the guest segment where it wants to generate more bookings?
An aggregate visibility metric cannot answer that.

The Hotel's Offering Was Relevant, Yet the Connection Did Not Appear Consistently
The property's publicly available offer included services and packages suited to family stays. Even so, the AI systems did not consistently connect the hotel with this guest scenario.
The test showed that the relationship between the property's attributes and the guest's needs was not represented consistently in the answers.
Possible explanations require a separate examination of sources:
• The hotel's own website may not state clearly enough for whom the offer is relevant and in which circumstances.
• External sources may not reinforce that positioning consistently.
• Competing hotels may be more closely associated with the same guest need.
• Information discovered by AI systems may be incomplete, inconsistent or out of date.
• Hotel communications may list services but provide too little evidence concerning specific guest scenarios.
The next audit stage must examine the sources, claims and substitute recommendations. First establish what the AI discovers, how it interprets that information, which sources it displays and which competitors it recommends instead.

The Same Number of Mentions May Conceal Different Performance
Both systems mentioned the hotel 15 times in 18 anonymous hotel-recommendation questions. That does not mean they understood or presented the property in the same way.
They may have differed in the scenarios where they recommended it, its position in the response, competing hotels listed alongside it, the qualities cited as justification and the sources shown.
Brand-name fact-checking prompts exposed another difference. A link to the hotel's official domain appeared in all 14 relevant ChatGPT answers, but in only 10 of the 14 Google AI Mode responses.
A displayed link does not prove that the system relied solely on that source. Nevertheless, the systems differed measurably in how often they surfaced the property's official website alongside their answers.
This is why combining different AI platforms into a single visibility score can be misleading.
One Incorrect Fact Can Become a Direct Commercial Risk
The audit examined not only whether the hotel appeared, but whether the systems described it accurately.
For a question involving business events, several answers included contradictory or partly outdated capacity figures. One system repeatedly returned a number that differed from the hotel's current official data.
When a potential client asks whether a venue can accommodate an event, an incorrect capacity figure may eliminate that hotel before an enquiry is ever submitted.
In that situation, positive descriptions matter far less than a single mistake affecting a business decision.
An AI recommendation audit must therefore go beyond counting brand mentions. Factual accuracy, source quality and the commercial consequences of errors are just as important.
One Answer Is Not a Measurement
An AI response is not a fixed position in a Google search ranking. Results may depend on wording, guest constraints, the model used, web sources available, location information and the moment of testing.
OpenAI explains that ChatGPT Search may rewrite a question into more targeted searches, while search results and citations may be incomplete, outdated or inaccurate.
Google similarly explains that its AI features may run several related searches and assemble responses from different web sources.
Sources: OpenAI and Google Search Central.
It is therefore not enough to ask once:
Which is the best wellness hotel?
That answer might be interesting, but it does not reveal a property's AI recommendation position. Measuring it calls for a repeatable question framework, multiple platforms, separate guest scenarios and a consistent scoring method.

Running the Questions Is Only the Beginning
Anyone can paste a few dozen prompts into an AI system. The professional challenge is turning those answers into a diagnosis that supports decisions.
That requires:
• Defining guest scenarios aligned with the hotel's business goals.
• Separating brand-name questions from unbranded questions.
• Coding answers consistently.
• Distinguishing a simple mention from a real recommendation and a position in a list.
• Identifying competing hotels that appear instead.
• Verifying sources and factual claims.
• Assessing the business significance of results.
• Repeating measurements after corrective actions.
The result should not be one visibility score. A useful audit identifies where the hotel enters the recommendation set and where it is missing, which competitors take its place, which sources shape answers, what information is absent or unreliable and which weaknesses genuinely matter commercially.
Five Management Questions About AI Recommendability
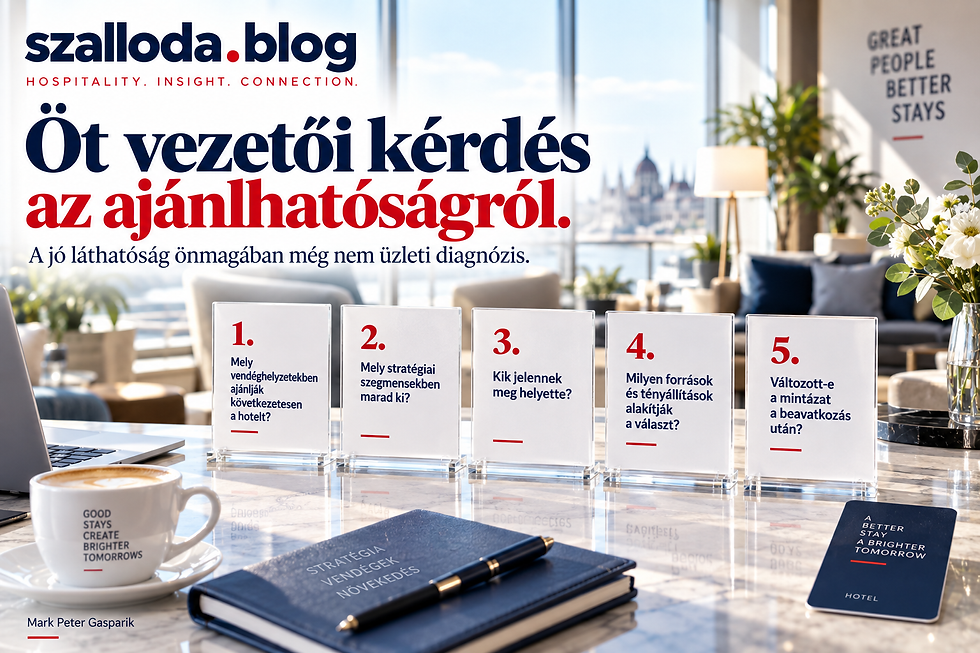
Following an AI audit, hotel management should have answers to at least five questions:
1. In which guest situations is the hotel recommended consistently?
2. In which strategic segments is it absent?
3. Which competing hotels are recommended in its place?
4. Which sources and factual claims shape the answers?
5. Did the recommendation pattern actually change after the interventions?
A report showing only how often a hotel's name appeared has counted visibility but has not yet produced a commercial diagnosis.
A Hotel Wins or Loses One Guest Scenario at a Time
The audited hotel appeared frequently in unbranded recommendations and consistently in certain guest scenarios. In other commercially important segments, it was rarely suggested. Some answers also gave inaccurate information about it.
The key management question is therefore not whether AI knows the property.
It is in which guest situations the hotel is recommended, which alternatives appear instead, and what evidence drives the decision.
Without those answers, the hotel does not really know its position in AI recommendations. Asking ChatGPT once is not a measurement — it is simply obtaining one answer.
Methodological Note
This analysis covers one anonymised Hungarian wellness hotel and one measurement wave from 2026. The test involved 21 prompts, two AI systems and two repetitions per prompt, yielding 84 answers.
The 30/36 result refers only to 36 unbranded hotel-recommendation runs. Two repetitions can help identify diagnostic patterns, but cannot establish precise probabilities or representative market conclusions.
About the Author
Mark Peter Gasparik specialises in AI recommendation and generative engine optimisation (GEO) strategy. His multi-platform audits examine the guest scenarios in which hospitality and tourism brands appear, the competitors recommended instead, the evidence and sources used and the potential commercial risks. His work is based on unbranded prompts, source verification and repeated baseline tests.
Contact: LinkedIn
Website: AuditUniversePro
This article was translated from the original Hungarian using artificial intelligence. The original language is Hungarian.


Comments